Pharmacophore an International Research Journal
Artificial intelligence models for drug discovery are commonly optimized within individual datasets, yet pharmaceutical prediction frequently involves assays with few observations, targets absent from model development, and compounds that occupy unfamiliar regions of chemical space. Under these conditions, a strong retrospective score does not establish that a model has learned information that can be transferred safely or usefully to a new task. This Original Pharmaceutical Meta-Learning Theory Article develops a conceptual account of how pharmaceutical models should learn across tasks while preserving the distinctions among assay similarity, target relatedness, chemical-space coverage, uncertainty, and experimental usefulness. The proposed contribution is a pharmaceutical meta-generalization framework in which transferable knowledge is conditioned on task provenance, an explicitly defined adaptation operation, a multidimensional description of distribution shift, uncertainty-aware deferral, leakage prevention, and progressively stronger evaluation. The framework treats assay sparsity, target novelty, and chemical-space shift as interacting but non-equivalent sources of difficulty. It further argues that task construction is part of the scientific hypothesis because decisions about episode composition, support examples, endpoint harmonization, and test partitions determine what a reported transfer result can mean. No single accuracy, ranking, or calibration measure is sufficient to demonstrate successful pharmaceutical meta-learning. Evaluation must instead test whether adaptation survives entity-disjoint, assay-disjoint, target-disjoint, temporal, and prospective conditions while remaining interpretable within a defined decision context. The framework is conceptual rather than empirically validated and does not establish mechanistic correctness, experimental success, clinical utility, regulatory acceptability, or deployment readiness. Its value lies in organizing the evidence and validation requirements needed to distinguish genuine learning across pharmaceutical tasks from memorization, inappropriate pooling, or misleading transfer.
Introduction
Machine learning and deep learning now influence molecular-property prediction, compound prioritization, target-related modeling, and other stages of drug discovery, but their growing technical reach has not removed the need to distinguish retrospective benchmark performance from practical pharmaceutical impact [1–3]. This distinction becomes especially important when models are expected to operate beyond the tasks, targets, and chemical distributions represented during development. A predictor may perform well within a familiar dataset while failing when transferred to an assay with different measurement practices, a biologically unfamiliar target, or compounds outside the structural coverage of its training set. The scientific problem is therefore not simply how to obtain a higher score from limited observations, but how to determine whether information learned elsewhere is relevant to the new pharmaceutical task.
The available chemical and biological data do not constitute a uniform learning environment. Bioactivity records can differ in assay protocol, endpoint definition, measurement scale, censoring, target annotation, compound representation, class balance, and curation history. These differences constrain the conclusions that can be drawn from apparently large data collections and mean that data availability cannot be treated as equivalent to data suitability [4]. Sparse pharmaceutical tasks are consequently embedded within heterogeneous evidence systems rather than isolated matrices of compounds and labels. A method that transfers information across tasks without accounting for this provenance may increase statistical efficiency while simultaneously weakening the scientific meaning of its predictions.
Interpretability does not resolve this problem by itself. Explanations may help identify molecular features, learned associations, or influential observations, but they do not independently establish causal mechanisms, experimental reproducibility, or prospective validity [5]. Similarly, uncertainty outputs may appear reassuring without being calibrated for a new assay or target, and scaffold-based test performance may remain optimistic when compounds are well covered by related training structures. The central evidentiary gap is therefore the absence of an integrated theory connecting what is transferred, how adaptation occurs, which form of novelty is being tested, how uncertainty should regulate use, and what level of evaluation is required before a transfer claim is considered pharmaceutically meaningful.
This article proposes a pharmaceutical meta-generalization framework for organizing those relationships. The framework is not a new empirically validated algorithm. It is a theoretical construct that defines successful meta-learning as conditional transfer within a documented task context. Its components are task provenance, a transferable relation learned across tasks, an adaptation operator, explicit assay–target–chemical shift geometry, an uncertainty gate, a leakage firewall, and an evaluation pathway extending toward prospective testing. The article’s central argument is that none of these components can be replaced by a single performance measure: a model may discriminate accurately while being poorly calibrated, adapt rapidly while exploiting leakage, generalize across compounds while failing on unseen targets, or produce plausible explanations without experimental confirmation.
Why Low-Data Pharmaceutical Tasks Require Learning across Tasks
Few-example molecular prediction provides a direct rationale for learning across pharmaceutical tasks. When an assay contains only a small number of labeled compounds, fitting an independent high-capacity predictor is likely to be unstable, overly dependent on the observed examples, or incapable of representing the relevant structure–activity relation. Cross-task learning offers an alternative by acquiring reusable representations, similarity functions, parameter priors, or adaptation rules from a distribution of related tasks. However, the validity of such transfer depends on how the task distribution is constructed, what inductive bias is learned, and whether evaluation reflects realistic low-data conditions [6–8]. Meta-learning is therefore valuable not because every sparse assay should borrow information from every other assay, but because carefully selected task relationships may provide prior structure that cannot be estimated reliably from the new task alone.
The operational unit of this reasoning is the adaptation task. A new pharmaceutical task is supplied with a limited support set, and the learner uses both prior cross-task knowledge and those task-specific observations to generate predictions for additional compounds. Recent ligand-based few-shot work illustrates how adaptation can be framed around a small set of activity-labelled compounds for a previously underrepresented task [9]. Yet the support set is not merely a convenient subsample. Its chemical diversity, label balance, assay fidelity, measurement uncertainty, and coverage of the intended prediction domain determine what adaptation is possible. A support set consisting of close analogues may permit accurate local interpolation while providing little evidence of broader chemical generalization.
The proposed framework therefore distinguishes transferable information from transferable relevance. Transferable information is any statistical structure learned across source tasks, including molecular representations, target embeddings, task prototypes, optimization parameters, or uncertainty patterns. Transferable relevance is the stronger condition that this information is appropriate for the new assay, target, chemical region, and decision. Meta-learning methods can improve statistical efficiency by reusing information, but they cannot infer pharmaceutical comparability solely from the presence of labels. The proposed framework consequently treats task relatedness as a scientific proposition that must be supported by provenance, biological context, chemical coverage, and observed adaptation behaviour rather than assumed from database co-location or endpoint naming.
Learning across tasks also changes the interpretation of failure. Poor performance may arise because the shared representation is inadequate, because the selected source tasks are unrelated, because the support set is uninformative, because adaptation overfits, or because the test compounds fall outside the supported chemical domain. Conversely, favourable performance may reflect valid transfer, but it may also reflect duplicated records, shared analogues, target overlap, or harmonization choices that reduce the effective novelty of the task. Cross-task learning is therefore conditional on data suitability rather than data volume alone [4]. Table 1 organizes the evidence, constructs, and interpretation boundaries needed to develop why low-data pharmaceutical tasks require learning across tasks within the article’s central argument.
Table 1. Evidence domains, core questions, scientific requirements, and interpretation boundaries for Why low-data pharmaceutical tasks require learning across tasks
|
Construct or evidence domain |
Core question |
Scientific basis |
Role in the article |
Failure or overclaiming risk |
Boundary statement |
|
Assay sparsity |
Is the task too poorly sampled to support reliable independent learning? |
Pharmaceutical assays often contain limited, imbalanced, noisy, or selectively measured observations. |
Establishes the need for prior information or inductive bias learned from other tasks. |
Treating every small dataset as evidence that meta-learning will be beneficial. |
Sparsity motivates cross-task learning but does not establish that suitable source tasks exist. |
|
Task provenance |
Are source and adaptation tasks comparable in endpoint, protocol, target definition, units, and curation? |
Experimental records can differ in how activities are generated, transformed, filtered, and annotated. |
Defines the admissible task distribution and constrains interpretation of transfer. |
Pooling nominally similar endpoints that represent different experimental quantities. |
Harmonization can support comparison but cannot make biologically or experimentally distinct tasks equivalent. |
|
Cross-task relatedness |
What scientific or statistical relation makes information from one task relevant to another? |
Tasks may share molecular determinants, target-family structure, assay context, or reusable representation features. |
Defines the transferable relation that the meta-learner is intended to capture. |
Interpreting learned similarity as mechanistic or causal similarity. |
Task relatedness is a testable assumption, not an automatic property of database membership. |
|
Support-set adequacy |
Do the available examples identify the task-specific relation needed for adaptation? |
Few-shot adaptation depends on the diversity, reliability, and domain coverage of the support compounds. |
Determines whether prior knowledge can be adjusted to the new task. |
Reporting adaptation from chemically redundant or selectively favourable examples. |
A small support set may enable local prediction without supporting broad chemical extrapolation. |
|
Adaptation behaviour |
Does the model use new-task evidence rather than merely reproduce its meta-trained prior? |
Adaptation may modify embeddings, prototypes, parameters, predictions, or uncertainty estimates. |
Separates genuine task-specific learning from frozen transfer or prior-task memorization. |
Attributing all performance to meta-learning when gains originate from pretraining or overlap. |
Rapid adaptation is not proof that the adapted relation is scientifically valid. |
|
Shift specification |
Which aspects of the new task are genuinely unseen? |
Novelty may concern assay conditions, target identity, molecular structure, time, or combinations of these factors. |
Converts generalization into a defined, falsifiable claim. |
Describing a random holdout as evidence of unseen-target or out-of-domain performance. |
No single split represents all forms of pharmaceutical novelty. |
|
Uncertainty and deferral |
Can the system identify predictions unsupported by the task evidence or training domain? |
Limited data and distribution shift can produce confident errors and unstable adaptation. |
Places a decision boundary around model use and permits abstention. |
Treating model confidence as calibrated uncertainty or evidence of correctness. |
Uncertainty must be evaluated under the intended shift and cannot establish mechanism, safety, or utility alone. |
|
Pharmaceutical usefulness |
Does cross-task learning improve a defined experimental or scientific decision? |
Drug discovery decisions involve assay cost, chemical feasibility, novelty, uncertainty, and downstream evidence requirements. |
Prevents benchmark optimization from becoming the sole success criterion. |
Equating predictive improvement with experimental, therapeutic, or commercial value. |
Meta-learning can support prioritization but cannot replace experimental confirmation or multidisciplinary judgement. |
Assay Sparsity, Target Novelty, and Chemical-Space Shift
The phrase “unseen task” is scientifically incomplete unless the source of novelty is specified. Molecular-learning benchmarks differ in endpoint type, dataset scale, label distribution, assessment metric, and splitting strategy, demonstrating that evaluation conditions must be matched to the structure of the prediction problem [10]. This article therefore proposes a three-axis pharmaceutical shift geometry comprising assay shift, target shift, and chemical-space shift. The axes are analytically distinct even when they occur together. Assay shift concerns how an endpoint is measured or defined; target shift concerns the biological entity or context to which predictions are transferred; and chemical-space shift concerns the structural, physicochemical, or representation-level distance between training and application compounds.
Assay sparsity is more than a low row count. Large bioactivity collections can remain sparse because only a small fraction of possible compound–assay combinations has been measured, because positive and negative observations are highly imbalanced, and because individual endpoints contain uneven evidence [11]. The missingness is also rarely random: compounds are selected according to project priorities, prior hypotheses, synthetic accessibility, historical screening cascades, and earlier experimental results. A meta-learner trained on this matrix may consequently learn institutional or experimental selection patterns alongside pharmacological relations. The proposed framework treats assay sparsity as a provenance-conditioned pattern of observed and unobserved evidence, requiring explicit description of endpoint identity, measurement process, missingness, support-set composition, and intended prediction population.
Chemical-space shift arises when application compounds are not adequately represented by the structures used for meta-training or adaptation. Such shift cannot be reduced to a binary distinction between “in distribution” and “out of distribution,” because novelty may involve scaffolds, substituent combinations, stereochemistry, molecular size, charge states, physicochemical properties, representation coverage, or local activity discontinuities. Real-world molecular out-of-distribution studies show that the mechanism used to construct the shift changes what is being tested and how model behaviour should be interpreted [12]. A scaffold split may reduce direct chemotype overlap, for example, while still leaving test compounds close to known analogues. The framework therefore requires chemical novelty to be specified through multiple coverage descriptions rather than inferred from a split label alone.
Target novelty introduces an additional transfer problem because ligand–activity relations depend on biological context as well as molecular structure. Protein representations can support interaction prediction when target identities differ from those encountered during training, suggesting a route toward biologically informed inductive transfer [13]. Nevertheless, target novelty is graded rather than absolute: an unseen protein may belong to a well-represented family, share homologous binding sites, interact with familiar ligands, or inherit information through external pretraining. Sequence novelty also does not establish functional novelty, mechanistic understanding, or therapeutic relevance. The most demanding setting is therefore a joint shift in which assay conditions, target context, and ligand chemotypes all depart from meta-training. Under that condition, success must be judged not only by predictive performance but also by calibration, coverage, leakage control, abstention behaviour, and eventual experimental confirmation.
Meta-Learning Design Choices for Pharmaceutical Prediction
Pharmaceutical meta-learning can be designed around representations, similarity metrics, task prototypes, optimization rules, parameter generators, or combinations of these elements. The proposed pharmaceutical meta-generalization framework does not prescribe a universally superior architecture. Instead, it asks what each design transfers, what evidence it requires from a new task, and how its uncertainty changes after adaptation. An evidential meta-model for molecular-property prediction demonstrates that meta-learning and uncertainty estimation can be constructed jointly, although an evidential output does not automatically guarantee calibration under every pharmaceutical shift [14]. Architecture selection must therefore follow the intended generalization claim rather than convenience alone.
Representation learning and adaptation perform related but distinct functions. A transferable representation attempts to retain molecular or biological features useful across tasks, whereas adaptation uses the limited evidence from a new task to modify predictions or decision boundaries. Few-shot and contrastive learning can be combined to address data limitation and imbalance, illustrating how representation objectives may support later task-specific inference [15]. Nevertheless, a representation that improves average benchmark performance may still encode scaffold frequency, assay-selection history, or other database regularities. Its transferability must be tested under the particular assay, target, and chemical shifts that the model is expected to encounter.
Metric-based and prototype-based designs define a new task through its relation to support examples or learned class summaries. Attribute-guided prototype construction illustrates how molecular attributes can shape task-specific prototypes in few-shot prediction [16]. Such designs can be useful when the support set is sufficiently representative, but prototype proximity is a statistical relation rather than evidence of common mechanism. A prototype can also be unstable when labels are noisy, classes are severely imbalanced, or support molecules occupy a narrow chemotype. The proposed framework therefore requires sensitivity analysis across support-set composition and an explicit account of what the learned distance is intended to represent.
Optimization-based, hypernetwork, and Bayesian approaches instead learn how task-specific parameters should be generated or updated. A Bayesian meta-learning hypernetwork shows how adaptation can be represented as a distribution over task-conditioned parameters rather than a single deterministic update [17]. This may support uncertainty-aware adaptation, but the resulting uncertainty remains conditional on the training tasks, prior assumptions, and support evidence. Meta-learning design should consequently be documented as a coupled choice among task representation, adaptation rule, parameter uncertainty, computational cost, and abstention behaviour. Table 2 organizes the evidence, constructs, and interpretation boundaries needed to develop meta-learning design choices for pharmaceutical prediction within the article’s central argument.
Table 2. Components, relationships, uncertainties, and validation needs within Meta-learning design choices for pharmaceutical prediction
|
Component or layer |
Inputs |
Core function |
Expected output |
Uncertainty or limitation |
Validation requirement |
|
Task-provenance representation |
Assay endpoint, protocol, target identity, activity units, compound identifiers, censoring and curation history |
Encodes the scientific context in which a task was generated |
A structured task description used to constrain transfer |
Metadata may be incomplete, inconsistent, or only superficially harmonized |
Demonstrate that provenance variables improve task comparability without creating hidden leakage |
|
Molecular representation |
Molecular graph, descriptors, fingerprints, conformational or physicochemical information |
Learns features transferable across compounds and tasks |
Compound embeddings for similarity, prediction or adaptation |
Learned features may reflect dataset frequency rather than relevant chemistry |
Test across scaffold, coverage and physicochemical shifts |
|
Biological representation |
Target sequence, structure, family, pathway or interaction context |
Represents target relatedness and supports transfer to unfamiliar biological entities |
Target or compound–target embeddings |
Sequence similarity may not correspond to functional or pharmacological similarity |
Evaluate target-disjoint and family-stratified settings |
|
Transferable-relation layer |
Source-task embeddings, molecular and biological representations, provenance information |
Estimates which source information is relevant to the adaptation task |
Task similarity, attention weights, priors or reusable parameters |
Relatedness may be confounded by shared compounds, assays or database practices |
Compare learned relatedness with biological, chemical and provenance-based controls |
|
Metric or prototype adaptation |
Support compounds, support labels and learned embedding space |
Builds a task-specific decision rule from distances or prototypes |
Adapted class probabilities, rankings or property estimates |
Sensitive to support-set imbalance, outliers and narrow chemotype coverage |
Repeat adaptation across multiple support-set compositions and sizes |
|
Optimization-based adaptation |
Meta-trained initialization, support loss and update rule |
Adjusts parameters using limited task-specific observations |
Task-adapted model parameters |
Can overfit noisy support labels or become unstable with few updates |
Compare with frozen-transfer and conventional fine-tuning baselines |
|
Hypernetwork or parameter-generation layer |
Task representation, support-set summary and learned parameter prior |
Generates task-conditioned weights or parameter distributions |
Deterministic or probabilistic task-specific parameters |
Parameter uncertainty may remain misspecified under unseen shifts |
Evaluate calibration and sensitivity under task- and entity-disjoint conditions |
|
Uncertainty gate |
Predictive distribution, ensemble variation, evidential parameters, coverage and OOD indicators |
Determines whether a prediction should be used, qualified or deferred |
Calibrated prediction, uncertainty statement or abstention |
Model confidence can remain high outside the supported domain |
Assess calibration, selective risk and abstention utility under the intended shift |
|
Leakage firewall |
Compound, target, assay, interaction, temporal and preprocessing lineage |
Prevents overlap from masquerading as transferable learning |
Auditable train, support, validation and test partitions |
Undocumented pretraining or external data can retain hidden overlap |
Perform entity-, relation-, series-, temporal- and pretraining-aware leakage audits |
|
Evaluation feedback layer |
Errors, calibration failures, abstentions, experimental outcomes and coverage analysis |
Revises task construction, adaptation and transfer assumptions |
Updated task ontology, split policy or model design |
Feedback can overfit the benchmark if reused without independent testing |
Confirm revisions on untouched or prospective evidence |
Task Construction, Adaptation, and Uncertainty Estimation
Task construction is part of the pharmaceutical hypothesis rather than a neutral preprocessing step. A task may correspond to an assay endpoint, target-specific activity problem, property endpoint, disease relationship, or another scientifically bounded prediction context. Curated bioactivity resources demonstrate the importance of standardizing compounds, targets, activity types, units, and quality filters before predictive use [18]. For meta-learning, these choices also determine which records form source tasks, support sets, query sets, and evaluation tasks. Combining incompatible measurements can create an apparently larger task distribution while weakening the meaning of adaptation.
Molecular uncertainty methods differ in scalability, calibration behaviour, error association, and sensitivity to the data-generating setting; no single uncertainty output guarantees reliable use under distribution shift [19–21]. The proposed framework therefore separates uncertainty into at least three questions: uncertainty in the observed endpoint, uncertainty arising from limited task evidence, and uncertainty caused by the distance between the new task and meta-training experience. These components may interact, but they should not be collapsed into an unqualified confidence score. An uncertainty estimate is useful only when its behaviour has been evaluated under the novelty conditions relevant to the intended decision.
The adaptation operator should be examined as an explicit scientific component. It may update model parameters, reweight source tasks, construct prototypes, infer a task embedding, or revise a predictive distribution. Joint adaptation and evidential modeling illustrate that the procedure used to learn the new task can influence both its prediction and its reported uncertainty [14]. Validation should therefore compare adaptation against a frozen representation, conventional fine-tuning, non-meta multitask learning, and simple similarity baselines under identical data partitions. Otherwise, gains attributed to meta-learning may originate from representation pretraining, greater model capacity, or favourable support-set selection.
The uncertainty gate converts uncertainty characterization into a bounded use rule. It can qualify predictions, reduce their decision weight, request additional experiments, or abstain when provenance is insufficient or the task lies outside supported coverage. Calibration studies in molecular prediction show why confidence should be compared with observed error rather than interpreted directly from network output [20]. Nevertheless, an abstention threshold cannot be universal. The acceptable uncertainty depends on assay cost, downstream consequence, alternative evidence, and whether the output supports exploratory ranking or a more consequential pharmaceutical decision. The gate is therefore a proposed governance function requiring application-specific validation.
Preventing Leakage and Misleading Transfer
Meta-learning is especially vulnerable to leakage because information can cross partitions through compounds, targets, analog series, assays, interactions, preprocessing choices, or external pretraining. Ligand-based classification benchmarks have been shown to reward memorization when structurally related examples occur across training and test sets [22]. In a meta-learning study, the same problem can arise at several levels: a query compound may resemble a source-task compound, an unseen assay may contain previously observed ligands, or a nominally new target may share highly informative relationships with meta-training targets. Reported adaptation then reflects retained familiarity rather than the intended novelty.
Chemical splitting should be designed around the generalization question rather than performed as an administrative final step. Structure-aware partitioning work in privacy-preserving pharmaceutical learning illustrates that molecular relationships and dataset properties can be controlled when assigning compounds to partitions [23]. For meta-learning, equivalent controls are needed across source tasks, support sets, model-selection data, and final evaluation tasks. A valid unseen-compound test must document analog relationships; a valid unseen-target test must address target homology and shared ligands; and an unseen-assay test must prevent protocol duplicates or transformed records from crossing partitions.
Entity-aware and relationship-aware splitting provides a stronger basis for such controls. DataSAIL demonstrates how similarity structures among biological and chemical entities can be incorporated into leakage-reducing partitions aligned with an intended prediction problem [24]. The proposed leakage firewall extends this principle to task provenance, support/query construction, temporal cutoffs, preprocessing, hyperparameter selection, and pretrained representations. Every information path that can reveal the evaluation task should be considered. Leakage reduction does not prove external validity, but it is necessary for interpreting any reported transfer as more than disguised interpolation.
Coverage bias remains even after obvious leakage is removed. Test compounds may be unevenly represented by the training chemical space, causing aggregate performance to depend strongly on which regions receive adequate coverage [25]. Accordingly, evaluation should report predictions and uncertainty across similarity, scaffold, physicochemical, and local-density strata. Strong average performance accompanied by failure in poorly covered regions should not be described as general chemical transfer. The framework therefore distinguishes the leakage question—whether information improperly crosses partitions—from the coverage question—whether the learner has enough relevant prior evidence to support a prediction.
Evaluation on Unseen Targets, Assays, and Prospective Settings
Evaluation must begin by defining the pharmaceutical claim. Application-oriented compound-activity benchmarks show that splits, task definitions, and assessment criteria should reflect the intended drug-discovery use rather than an abstract preference for one metric [26]. Within-task discrimination, ranking, calibration, and support-set sensitivity may provide initial evidence, but they do not establish adaptation to an unseen assay or target. The proposed evaluation ladder therefore progresses from controlled internal checks to explicit chemical, assay, target, joint, temporal, and prospective shifts. Each rung answers a different question and supports a correspondingly bounded interpretation.
Unseen-entity evaluation requires inductive rather than transductive reasoning. Work on drug repurposing demonstrates why models should be tested when relevant entities or relationships are absent from training rather than merely when individual links are withheld [27]. An unseen-target evaluation should therefore exclude the target from meta-training and document information that may still transfer through homologues, shared ligands, pathways, or pretrained biological representations. Likewise, an unseen-assay evaluation should describe differences in endpoint definition and protocol. A label such as “held-out task” is insufficient unless the mechanism of novelty is transparent.
Prospective experimental evaluation supplies stronger evidence because predictions are generated before new assay outcomes are known. Deep-learning-guided antibiotic discovery illustrates how model-prioritized compounds can be tested experimentally beyond the immediate training collection [28]. Such work demonstrates the evidentiary value of prospective confirmation, but it does not validate meta-learning generally or establish transfer to every target, endpoint, or therapeutic area. Prospective studies should predefine candidate-selection rules, assay procedures, comparators, uncertainty handling, and reporting of unsuccessful predictions to reduce selective confirmation.
Prospective chemical novelty and explanation should also be evaluated separately. The discovery of a structural antibiotic class through explainable deep learning shows that structurally distinct predictions can be prioritized and experimentally investigated, while model explanations remain hypotheses requiring scientific interpretation [29]. A complete meta-learning evaluation should therefore report what was unseen, why the model considered transfer admissible, whether uncertainty was calibrated, which predictions were deferred, and what experimental evidence followed. Table 3 organizes the evidence, constructs, and interpretation boundaries needed to develop evaluation on unseen targets, assays, and prospective settings within the article’s central argument.
Table 3. Evaluation, implementation, and research priorities arising from Learning How to Learn from Sparse Assays, Unseen Targets, and Shifting Chemical Spaces in Drug Discovery
|
Evaluation dimension |
What must be tested |
Suitable evidence or assessment |
Failure signal |
Interpretive limitation |
Decision relevance |
|
Internal adaptation validity |
Whether the model uses support evidence and improves over non-adapted alternatives |
Frozen-transfer, fine-tuning, multitask and simple-similarity comparators under identical partitions |
No consistent adaptation gain or extreme sensitivity to support composition |
Internal adaptation does not establish external generalization |
Determines whether the meta-learning mechanism adds value within a controlled task |
|
Support-set robustness |
Whether adaptation is stable across plausible small support sets |
Repeated support sampling, class-balance perturbation, label-noise sensitivity and chemotype coverage analysis |
Predictions change substantially after minor support-set changes |
Stability within sampled supports may not persist under assay shift |
Indicates how much task-specific evidence is needed before predictions are usable |
|
Unseen-compound evaluation |
Whether predictions extend beyond familiar analogues and training coverage |
Scaffold-aware, series-aware, similarity-stratified and physicochemical-shift tests |
Performance or calibration collapses in low-coverage regions |
No single split represents all forms of chemical novelty |
Supports bounded compound prioritization outside familiar series |
|
Unseen-assay adaptation |
Whether the learner can adapt across endpoint or protocol differences |
Assay-disjoint tasks with explicit provenance and small support sets |
Apparent gain disappears after protocol or endpoint harmonization is controlled |
Retrospective metadata may not describe all experimental differences |
Tests whether cross-assay transfer can inform a newly established assay |
|
Unseen-target transfer |
Whether predictions remain useful for targets absent from meta-training |
Target-disjoint evaluation stratified by family, homology and shared-ligand exposure |
Success is confined to close homologues or previously associated ligands |
Sequence novelty is not equivalent to functional novelty |
Supports experimental prioritization for a new biological target |
|
Joint target–chemical shift |
Whether transfer survives simultaneous biological and chemical novelty |
Entity-disjoint and relationship-disjoint partitions with two-dimensional coverage reporting |
One familiar axis masks failure on the other |
Sparse joint-shift cells can produce unstable estimates |
Represents a demanding test of general pharmaceutical transfer |
|
Temporal evaluation |
Whether performance persists on evidence generated after model development |
Immutable data snapshots, predeclared cutoff dates and forward-time testing |
Performance degrades as assay practice or chemical priorities change |
Time is an imperfect proxy for scientific novelty |
Tests whether the system remains informative for future project decisions |
|
Uncertainty and abstention |
Whether uncertainty identifies unsupported tasks and compounds |
Calibration, proper scoring rules, selective-risk analysis, OOD detection and deferral utility |
Confident errors or indiscriminate abstention under shift |
Thresholds are endpoint- and consequence-specific |
Determines when additional evidence or human review should be required |
|
Prospective experimental evaluation |
Whether prioritized predictions are confirmed in newly conducted experiments |
Predeclared selection policy, experimental assays, comparator strategy and negative-result reporting |
Selective confirmation, protocol changes or failure to test uncertain predictions |
One campaign does not establish universal utility |
Connects computational transfer to actual experimental prioritization |
|
Pharmaceutical decision consequence |
Whether meta-learning improves a defined decision under real resource constraints |
Prospective workflow comparison, expert assessment and resource-normalized utility |
Metric improvement does not change experimental or portfolio decisions |
Utility varies by organization, endpoint and development stage |
Establishes whether the model supports a meaningful research decision |
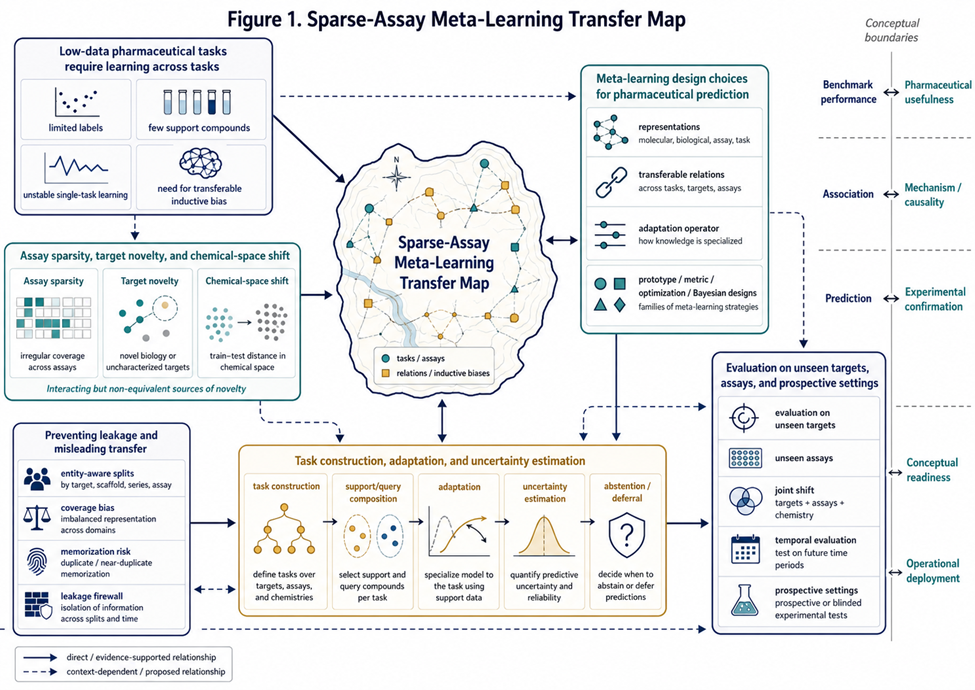
Figure 1 presents the sparse-assay meta-learning transfer map, showing how the article’s key components and boundaries are connected within evaluation on unseen targets, assays, and prospective settings.
|
|
|
Figure 1. Sparse-Assay Meta-Learning Transfer Map |
The figure is an original conceptual synthesis that organizes the article’s central contribution across low-data pharmaceutical tasks require learning across tasks, assay sparsity, target novelty, and chemical-space shift, assay sparsity, target novelty, chemical-space shift, meta-learning design choices for pharmaceutical prediction. Arrows and grouping indicate proposed or evidence-supported relationships rather than measured effect sizes. The figure does not represent a validated predictive model, regulatory determination, clinical recommendation, or deployment-ready system.
Limitations and Boundary Conditions
The pharmaceutical meta-generalization framework is a conceptual synthesis rather than a validated predictive architecture. Its components describe conditions under which transfer claims may be made more precise, but they do not establish that task provenance can always be recovered, that task relatedness can be measured correctly, or that assay, target, and chemical-space shifts can be separated cleanly. Molecular OOD definitions remain dependent on how novelty is constructed [12]. In practice, multiple shifts may occur simultaneously, and retrospective datasets may not contain enough information to identify their origins.
The framework also inherits limitations from the available evidence. Pharmaceutical few-shot studies use heterogeneous datasets, task definitions, support-set procedures, model classes, and evaluation conditions. Comparisons across studies therefore cannot be interpreted as a direct ranking of meta-learning designs. Explanations remain associations with learned model behaviour rather than proof of pharmacological mechanism [5]. Uncertainty estimates can be miscalibrated, and prospective evidence from one compound class or assay cannot establish general applicability across modalities, targets, organizations, or development stages.
The framework cannot determine synthesizability, developability, safety, therapeutic efficacy, clinical utility, or regulatory acceptability from molecular predictions alone. Even prospectively confirmed activity remains conditional on assay validity and does not establish broader therapeutic value. Prospective antibiotic-discovery studies demonstrate an important level of experimental evidence, but their success does not validate a universal transfer system [28]. Misuse would occur if the framework were treated as an operational approval process, a replacement for scientific review, or evidence that calibrated predictions can bypass experimental confirmation.
Research Agenda and Implementation Priorities
The first research priority is a provenance-rich pharmaceutical task ontology. It should represent assay endpoints, protocols, targets, measurement units, censoring, compound identity, class balance, curation, and temporal lineage in a form usable for episode construction. Curated bioactivity resources provide an important foundation but do not by themselves establish which records constitute scientifically comparable meta-learning tasks [18]. Future studies should test whether provenance-aware task definitions produce more stable adaptation and more interpretable failure patterns than tasks formed solely from database labels or target names.
The second priority is a shared evaluation infrastructure for explicit shift geometry and leakage control. Challenge sets should distinguish unseen compounds, assays, targets, interactions, temporal periods, and joint shifts. Entity-aware splitting methods can reduce information leakage when partitions are aligned with the intended generalization problem [24]. Reporting should additionally document pretraining corpora, analog-series overlap, target homology, support-set selection, hyperparameter access, and chemical coverage. These practices would make it possible to determine whether an apparent improvement originates from transferable learning, familiar entities, or benchmark construction.
The third priority is staged prospective implementation. Application-oriented benchmarks can first test whether models remain useful under realistic retrospective partitions [26]. Subsequent studies should evaluate calibration and abstention because molecular confidence does not guarantee reliability under new tasks [20]. Coverage analysis should identify regions where prior evidence is insufficient [25]. Only then should predeclared prospective experiments compare meta-learning-assisted prioritization with established workflows, including negative outcomes and human overrides. Prospective confirmation can strengthen an application-specific claim, but implementation should remain bounded by scientific oversight and independent replication [28].
Conclusion
Learning from sparse assays, unseen targets, and shifting chemical spaces requires more than transferring a pretrained representation or optimizing an aggregate performance measure. The original contribution of this article is a pharmaceutical meta-generalization framework that connects task provenance, transferable relations, adaptation, explicit shift geometry, uncertainty-based deferral, leakage prevention, and progressively stronger evaluation. The framework makes transfer claims conditional and falsifiable: investigators must specify what is unseen, what information is shared across tasks, how the new task changes the model, where uncertainty limits use, and what evidence separates retrospective performance from pharmaceutical usefulness. It does not establish a universally valid algorithm, causal mechanism, experimental outcome, clinical benefit, regulatory status, or deployment-ready process. Its intended role is to guide theory building, benchmark construction, reporting, and prospective validation so that learning across tasks is distinguished from inappropriate pooling, structural memorization, unsupported extrapolation, and misleading confidence.
Acknowledgments: None
Conflict of interest: None
Financial support: None
Ethics statement: None